


Matrix multiplication forms the product  of two matrices
 and
 , defined as
 |
(1)
|
where  is summed over for all possible values of
 and
 and the notation above uses the Einstein
summation convention. The implied summation over repeated indices without the
presence of an explicit sum sign is called Einstein
summation, and is commonly used in both matrix and
tensor analysis. Therefore, in order for matrix multiplication to be defined, the
dimensions of the matrices
must satisfy
 |
(2)
|
where  denotes a matrix with
 rows and
 columns. Writing out the product explicitly,
 |
(3)
|
where
 |  |  |
(4)
|
 |  |  |
(5)
|
 |  |  |
(6)
|
 |  |  |
(7)
|
 |  |  |
(8)
|
 |  |  |
(9)
|
 |  |  |
(10)
|
 |  |  |
(11)
|
 |  |  |
(12)
|
Matrix multiplication is associative, as can be seen by taking
 |
(13)
|
where Einstein summation is again used. Now, since  ,
 ,
and
 are scalars, use the associativity
of scalar multiplication to write
 |
(14)
|
Since this is true for all  and
 , it must be true that
 |
(15)
|
That is, matrix multiplication is associative. The product can therefore be written
 |
(16)
|
without ambiguity. Due to associativity, the  matrices over a fixed ring form a semigroup under multiplication.
Matrix multiplication is also distributive. If  and
 are
 matrices and
 and
 are
 matrices, then
 |  |  |
(17)
|
 |  |  |
(18)
|
Since  matrices form an Abelian group
under addition,
 matrices form a ring.
However, matrix multiplication is not, in general, commutative. Two diagonal matrices of the same size commute when their entries belong to a commutative ring.
For compatibly partitioned block diagonal matrices, the product is obtained by multiplying corresponding diagonal blocks:
 |
(19)
|
AlphaTensor, a reinforcement-learning system developed by DeepMind, found exact matrix multiplication algorithms matching or improving known
ranks for several small matrix
sizes. For example, it found a method for multiplying  matrices over
 using 47 products of scalars.
This improves on the 49 multiplications obtained by applying Strassen's
formulas twice (Fawzi et al. 2022).
Tomar (2026) reported that the tensor decomposition rank of  matrix multiplication over the finite field
 is exactly 23. This also gives the
lower bound 23 for bilinear algorithms with integer coefficients. This does not establish optimality over
an arbitrary field of characteristic
zero. Tomar (2026) reports two Lean proofs checking exhaustive-search certificates.
In one, the largest checks use compiled code as well as the proof kernel. In the
version of Oct. 19, 2026, a second proof evaluates every check in the kernel,
and its final theorem is reported to depend only on Lean's three standard axioms.
Ivanov (2026) reported that every exact bilinear algorithm for multiplying two  matrices over any field
requires at least 21 products of linear functionals
of the two inputs. Together with Laderman's algorithm
(Laderman 1976), the claimed bound gives
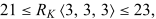 |
(20)
|
where  is the tensor decomposition rank of
 matrix multiplication over the
field
 . The claim includes every characteristic
and does not determine the exact tensor decomposition
rank over a general field. Ivanov reports substantial
ChatGPT/Codex assistance with the mathematics and Lean formalization. As of Oct. 15,
2026, the project and registry reported successful machine checks, but independent
specialist review had not been reported.
The matrix multiplication exponent measures the asymptotic number of arithmetic operations needed to multiply two  matrices.
It concerns growing sizes rather than the number of multiplications in a particular
small matrix product.

 Matrix Multiplication over Every Field." Oct. 12, 2026.
 Matrices Using 23 Multiplications." Bull. Amer.
Math. Soc. 82, 126-128, 1976.
 Matrix Multiplication over
 Is 23." 8 Oct 2026.