Linear source coding compresses a random source vector by applying a linear transformation, while allowing an arbitrary decoding map. For a binary source
 ,
an encoder has the form
 with a binary
 matrix
 , and the rate is
 . In lossy coding, distortion can be measured by the expected
fraction of incorrectly reconstructed bits.
For independent Bernoulli bits with parameter  and allowed distortion
 , the optimal asymptotic rate for linear encoding
is
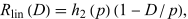 |
where 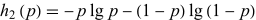 is binary information entropy and
 denotes the base-2 logarithm. This rate is achieved by compressing
a fraction
 of the source losslessly and estimating the remaining bits by zero.
The unrestricted rate-distortion function is 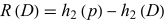 ,
which is smaller at interior distortions. Thus linearity imposes a genuine cost even
though linear encoders suffice for asymptotically lossless compression.
Wu (2026) proved the optimality of the linear rate for all  , answering the question of Massey and extending Ancheta's
 result, both documented in that paper. GPT-5.6 Sol discovered the proof
in an author-guided process, and Wu simplified and checked it. Independent external
review had not been reported as of Sep. 7, 2026.